Enterprise Knowledge Platform / RAG + Agent
My Company Brain
A multi-knowledge-base workspace for teams, organizing document knowledge, relational knowledge, knowledge pages, and an assistant behind one governable surface.
- Project scope
- 3 knowledge paths
- Current status
- No longer in development
- My role
- Independent developer
Technology
- TypeScript
- Python
- PostgreSQL
- Neo4j
- Docker
- RAG
- GraphRAG
What it solves
Development has stopped. This historical case study preserves the implemented features and the validation scope recorded at the time.
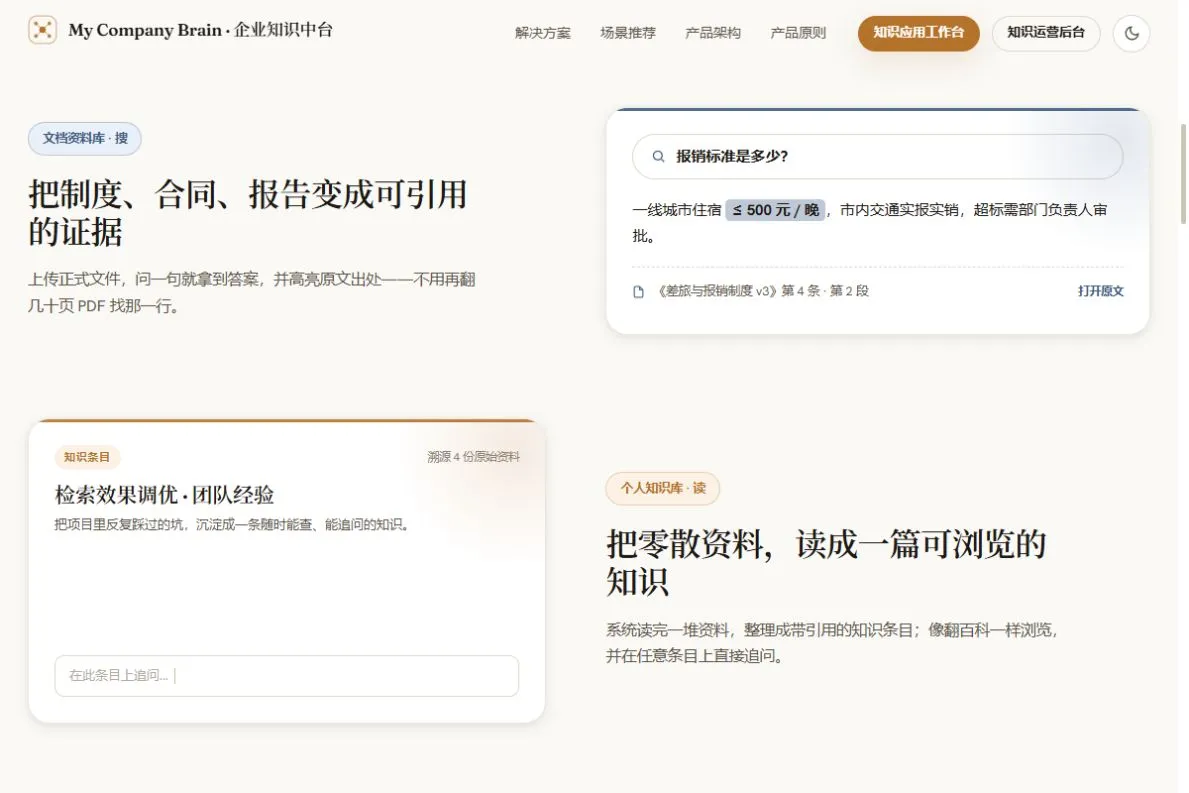
My Company Brain gives enterprise teams one governable workspace for knowledge sources, business scenarios, and traceable answers. Team members can choose a path that matches the material, ask follow-up questions, and inspect sources while public, private, and team authorization scopes constrain each retrieval.
Core capabilities
- Manage knowledge sources and visibility
- Import documents, tables, and knowledge pages
- Create business scenarios and follow-up tasks
- Ask follow-up questions across knowledge paths
- Inspect passage, page, table, and image sources
- Govern users, knowledge assets, and system state
How it works
- Create a knowledge source
- Import material
- Ask a question
- Inspect the answer and sources
Members first create a knowledge source and set its visibility, then import material or knowledge pages. They choose a business scenario, ask a question across the suitable paths, and open passage, page, table, and image sources behind the answer.
Project highlights
Match each knowledge type to the right path
The repository’s Agent Gateway routes requests by material type: Nano Brain handles pages, facts, and links; Traditional RAG handles document and table retrieval; and GraphRAG handles entities and relationships. The product result is one reusable workspace without forcing every knowledge type into one index.
Combine knowledge while preserving sources
Global Q&A can merge multiple knowledge paths in one answer while returning passage/page/table/image sources, so a user can move from a conclusion back to the material behind it. The repository’s cross-module orchestration and shared source model provide that traceability instead of concatenating uncited text.
The August update distinguishes retrieved material from sufficient evidence. Global Q&A selects deterministic supporting evidence and passes at most three selected sources to the answer model. Traditional RAG scenarios add answer / partial / refuse / clarify decisions: unsupported numbers or conflicting versions and entities lead to refusal or clarification, while partial answers state their limits. A second check validates generated numbers and identifiers against the selected evidence. These are code-inspection findings, not completed acceptance of answer quality on real business material.
Enforce access rules inside retrieval
public/private/team authorization is rechecked at module query boundaries rather than only hidden in the UI. The unified API and Agent Gateway establish the entry boundary, but each knowledge query carries visibility filtering again so a caller cannot bypass the interface and read unauthorized material.
System architecture
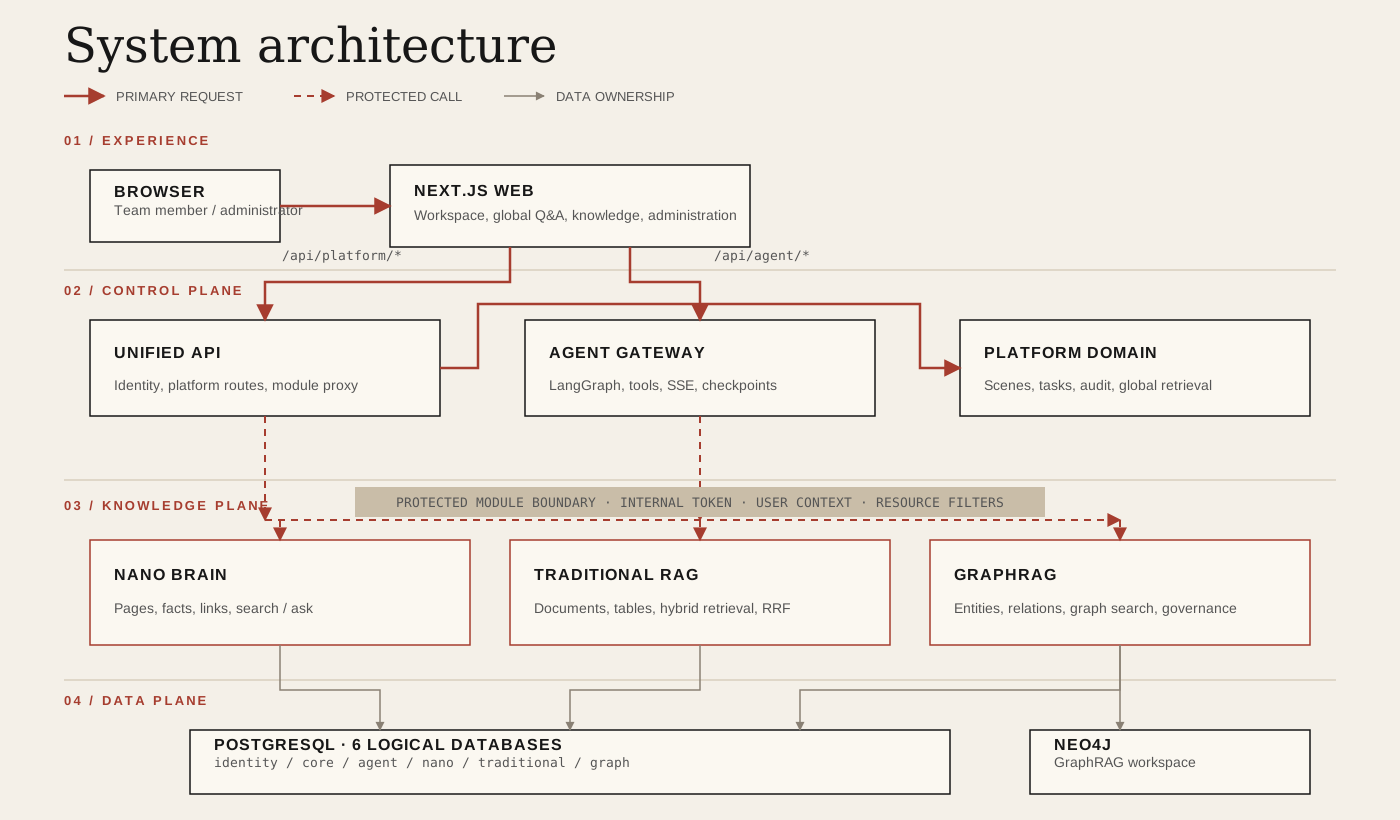
The Web layer enters only through the unified API, while the Agent Gateway orchestrates Nano Brain, Traditional RAG, and GraphRAG. Identity, platform, Agent, and the three knowledge paths use six logical PostgreSQL databases, with Neo4j dedicated to GraphRAG data.
Project scope
The current scope is a self-hosted team knowledge workspace, with claims grounded in the repository code, Compose definitions, and local runtime boundary. It does not claim production HA, enterprise SSO, or large-scale load capability; those scenarios require separate deployment, identity, and load-test validation.